Try it
Copy the code ↓- Data source
- Decision schema
- Model inference
- Structured result
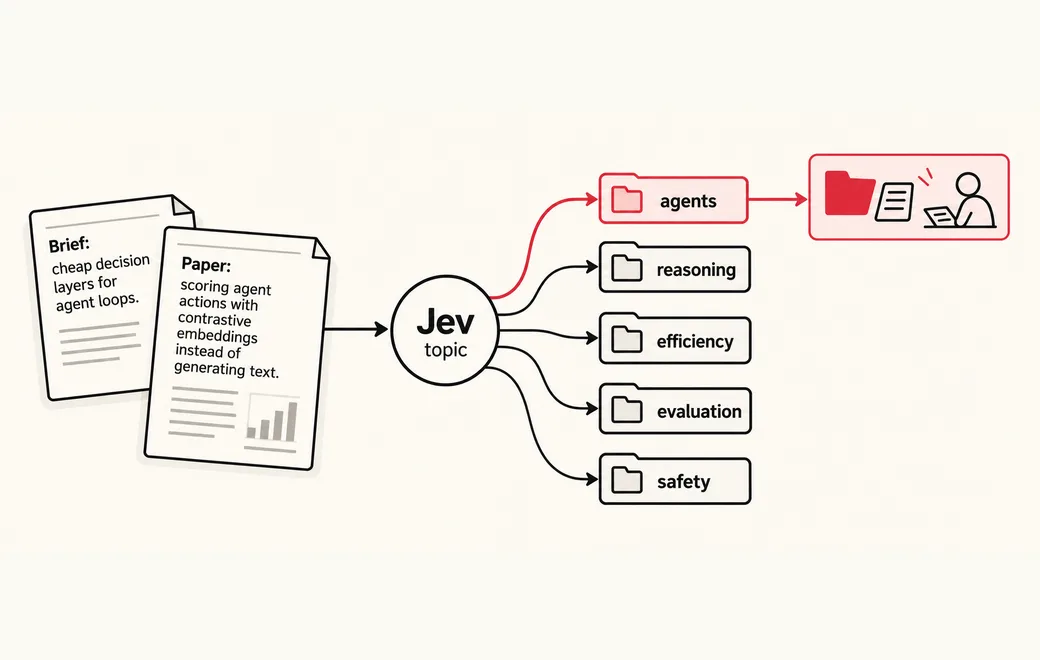
2 Decision schema 3 typed questions
topicchoiceagentsreasoningefficiencyevaluationsafetyotherrelevancescoreoff_topictangentialrelevantmust_readneeds_full_readnoulprobability 0–1
3 Model inference typesafe/jev-1.13
Waiting for a run.
4 Structured result
Raw JSON
Run the demo to see the JSON answers, the highlighted pick and the final action.
FLATKEY_API_KEY and run.curl -sS https://router.flatkey.ai/api/alpha/decisions \
-H "Authorization: Bearer $FLATKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "typesafe/jev-1.13",
"state": "Brief: cheap decision layers for agent control loops.\n\nPaper: Scoring agent actions with contrastive embeddings. Abstract: Instead of generating text, we embed the agent state and each candidate action separately and score them by similarity, so action embeddings can be cached. We evaluate on computer-use, gaming and tool-calling tasks.",
"questions": {
"topic": {
"type": "choice",
"instructions": "Which topic best describes the paper'\''s main contribution?",
"criteria": {
"agents": "Agent architectures, tool use and planning",
"reasoning": "Reasoning, math and chain-of-thought methods",
"efficiency": "Faster or cheaper inference, distillation, small models",
"evaluation": "Benchmarks, evals and measurement",
"safety": "Alignment, robustness and security",
"other": "None of these"
}
},
"relevance": {
"type": "score",
"instructions": "How relevant is this paper to the research brief in the state?",
"criteria": [
"off_topic",
"tangential",
"relevant",
"must_read"
]
},
"needs_full_read": {
"type": "noul",
"instructions": "The abstract makes a claim that should be checked in the full paper before it is cited or dismissed."
}
}
}'// Node.js 18+ (built-in fetch). Run: FLATKEY_API_KEY=... node jev.mjs
const body = {
"model": "typesafe/jev-1.13",
"state": "Brief: cheap decision layers for agent control loops.\n\nPaper: Scoring agent actions with contrastive embeddings. Abstract: Instead of generating text, we embed the agent state and each candidate action separately and score them by similarity, so action embeddings can be cached. We evaluate on computer-use, gaming and tool-calling tasks.",
"questions": {
"topic": {
"type": "choice",
"instructions": "Which topic best describes the paper's main contribution?",
"criteria": {
"agents": "Agent architectures, tool use and planning",
"reasoning": "Reasoning, math and chain-of-thought methods",
"efficiency": "Faster or cheaper inference, distillation, small models",
"evaluation": "Benchmarks, evals and measurement",
"safety": "Alignment, robustness and security",
"other": "None of these"
}
},
"relevance": {
"type": "score",
"instructions": "How relevant is this paper to the research brief in the state?",
"criteria": [
"off_topic",
"tangential",
"relevant",
"must_read"
]
},
"needs_full_read": {
"type": "noul",
"instructions": "The abstract makes a claim that should be checked in the full paper before it is cited or dismissed."
}
}
};
const res = await fetch("https://router.flatkey.ai/api/alpha/decisions", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.FLATKEY_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify(body),
});
if (!res.ok) throw new Error(`Jev request failed: ${res.status} ${await res.text()}`);
const { answers, usage } = await res.json();
console.log(JSON.stringify(answers, null, 2), usage);# Python 3.8+ (pip install requests). Run: FLATKEY_API_KEY=... python jev.py
import json, os, requests
body = json.loads(r"""{
"model": "typesafe/jev-1.13",
"state": "Brief: cheap decision layers for agent control loops.\n\nPaper: Scoring agent actions with contrastive embeddings. Abstract: Instead of generating text, we embed the agent state and each candidate action separately and score them by similarity, so action embeddings can be cached. We evaluate on computer-use, gaming and tool-calling tasks.",
"questions": {
"topic": {
"type": "choice",
"instructions": "Which topic best describes the paper's main contribution?",
"criteria": {
"agents": "Agent architectures, tool use and planning",
"reasoning": "Reasoning, math and chain-of-thought methods",
"efficiency": "Faster or cheaper inference, distillation, small models",
"evaluation": "Benchmarks, evals and measurement",
"safety": "Alignment, robustness and security",
"other": "None of these"
}
},
"relevance": {
"type": "score",
"instructions": "How relevant is this paper to the research brief in the state?",
"criteria": [
"off_topic",
"tangential",
"relevant",
"must_read"
]
},
"needs_full_read": {
"type": "noul",
"instructions": "The abstract makes a claim that should be checked in the full paper before it is cited or dismissed."
}
}
}""")
res = requests.post(
"https://router.flatkey.ai/api/alpha/decisions",
headers={"Authorization": f"Bearer {os.environ['FLATKEY_API_KEY']}"},
json=body,
timeout=60,
)
res.raise_for_status()
data = res.json()
print(json.dumps(data["answers"], indent=2), data.get("usage"))No Flatkey key yet? Get one for Jev 1.13 →
About this use case
Who / when
Audience
- research teams tracking arXiv and conference firehoses
- analysts and literature-review builders
- developers building paper explorers and reading-list bots
Triggers
- hundreds of new papers a week, a handful worth reading
- a literature review needs every paper tagged against the same taxonomy
- a reading-list bot should surface only papers relevant to a brief
- LLM-per-paper classification costs more than the summaries
The workflow
- 01Paper stateBrief, title and abstract or summaryInput
- 02ChoiceTopic from a fixed taxonomyJev
- 03Score + NoulRelevance to the brief, full-read flagJev
- 04Code gateFile, shortlist or leave for a humanYour code
Question shape
{
  "topic": {
    "type": "choice",
    "instructions": "Which topic best describes the paper's main contribution?",
    "criteria": {
      "agents": "Agent architectures, tool use and planning",
      "reasoning": "Reasoning, math and chain-of-thought methods",
      "efficiency": "Faster or cheaper inference, distillation, small models",
      "evaluation": "Benchmarks, evals and measurement",
      "safety": "Alignment, robustness and security",
      "other": "None of these"
    }
  },
  "relevance": {
    "type": "score",
    "instructions": "How relevant is this paper to the research brief in the state?",
    "criteria": [
      "off_topic",
      "tangential",
      "relevant",
      "must_read"
    ]
  },
  "needs_full_read": {
    "type": "noul",
    "instructions": "The abstract makes a claim that should be checked in the full paper before it is cited or dismissed."
  }
}
Gate policy
≥ 0.90
File under the topic; add must-reads to this week's list.
0.65–0.90
File under the topic; a researcher skims the abstract.
< 0.65
Leave in the unsorted inbox for a human pass.
Failure modes
Pre-launch checks before you trust auto-routing:
- Interdisciplinary papers that fit two topics;
- Abstracts that oversell; relevance judged on claims, not results;
- Taxonomy drift: topics added or split without updating descriptions;
- Very long inputs: send a summary or abstract, not the whole PDF;
- Near-duplicate versions of the same paper;
FAQ
How cheap is it at scale?
Sammy's write-up of the Jev Engineering pattern (post below) cites 10,000 decisions for $0.42 and 1,018 papers sorted for $0.08. The pattern is "LLM writes → Jev decides → code acts": a generative model can summarize each paper, Jev classifies, code files the result.
Should I send the whole paper?
Usually not. Title plus abstract, or a short LLM summary, carries the signal for topic and relevance and keeps input cost low. Keep the full text for papers flagged needs_full_read.
Can I use my own taxonomy?
Yes. The topic question is just a Choice with your categories. Keep descriptions distinct and include an "other" option so papers outside your taxonomy don't get forced into a wrong bucket.
Can I bring my own API key?
Yes. Try the free demo above without signing in. To run it live on your own text, sign in with Google and connect a Flatkey or OpenRouter key (a quick test call runs when you save it). Manage or delete it anytime under Dashboard → BYOK. Keys are stored encrypted on the server, used only for runs you trigger, and never sent back to the browser. Need a Flatkey key? Get one for Jev 1.13 on Flatkey.
Is this the official TypeSafe Jev product page?
No. jev-llm.com is an independent research and practice site. Verify pricing, models and terms at the original TypeSafe sources.
Sources
Now Jev Engineering adds the decision layer every agent stack is missing LLM writes → Jev decides → code acts … three shapes of answer: choice: one winner from a closed list score: a position on your rubric noul: the probability that a statement holds … 10,000 decisions for $0.42 1,018 papers sorted for $0.08
— @sammy_capital View the post on X →
Wire this gate with your own key
Bring your own key through Flatkey / OpenRouter. Keep exact checks in code.