Try it
Copy the code ↓- Data source
- Decision schema
- Model inference
- Structured result
2 Decision schema 3 typed questions
verdictchoicepassretryfailinconclusivequalityscorepoorfairgoodexcellentneeds_human_reviewnoulprobability 0–1
3 Model inference typesafe/jev-1.13
Waiting for a run.
4 Structured result
Raw JSON
Run the demo to see the JSON answers, the highlighted pick and the final action.
FLATKEY_API_KEY and run.curl -sS https://router.flatkey.ai/api/alpha/decisions \
-H "Authorization: Bearer $FLATKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "typesafe/jev-1.13",
"state": "Goal: update staging deploy and verify health check returns 200. Agent steps: (1) ran git pull on staging host, (2) restarted the service, (3) claimed \"deploy complete and healthy\". Missing: no curl or health-check command was run; last log line is only the restart. Required verification step was skipped. Retries so far: 0.",
"questions": {
"verdict": {
"type": "choice",
"instructions": "Judge the agent run against the stated goal and required checks.",
"criteria": {
"pass": "The agent completed the goal and met the required verification steps with supporting evidence",
"retry": "The run is incomplete or skipped a required check, but another attempt with the same setup is warranted",
"fail": "The agent clearly missed the goal, violated policy, or produced incorrect or unsafe output",
"inconclusive": "The transcript lacks enough evidence to judge pass or fail"
}
},
"quality": {
"type": "score",
"instructions": "Overall run quality ignoring self-claims of success.",
"criteria": [
"poor",
"fair",
"good",
"excellent"
]
},
"needs_human_review": {
"type": "noul",
"instructions": "A human or chat-model judge should review this run before the score is trusted."
}
}
}'// Node.js 18+ (built-in fetch). Run: FLATKEY_API_KEY=... node jev.mjs
const body = {
"model": "typesafe/jev-1.13",
"state": "Goal: update staging deploy and verify health check returns 200. Agent steps: (1) ran git pull on staging host, (2) restarted the service, (3) claimed \"deploy complete and healthy\". Missing: no curl or health-check command was run; last log line is only the restart. Required verification step was skipped. Retries so far: 0.",
"questions": {
"verdict": {
"type": "choice",
"instructions": "Judge the agent run against the stated goal and required checks.",
"criteria": {
"pass": "The agent completed the goal and met the required verification steps with supporting evidence",
"retry": "The run is incomplete or skipped a required check, but another attempt with the same setup is warranted",
"fail": "The agent clearly missed the goal, violated policy, or produced incorrect or unsafe output",
"inconclusive": "The transcript lacks enough evidence to judge pass or fail"
}
},
"quality": {
"type": "score",
"instructions": "Overall run quality ignoring self-claims of success.",
"criteria": [
"poor",
"fair",
"good",
"excellent"
]
},
"needs_human_review": {
"type": "noul",
"instructions": "A human or chat-model judge should review this run before the score is trusted."
}
}
};
const res = await fetch("https://router.flatkey.ai/api/alpha/decisions", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.FLATKEY_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify(body),
});
if (!res.ok) throw new Error(`Jev request failed: ${res.status} ${await res.text()}`);
const { answers, usage } = await res.json();
console.log(JSON.stringify(answers, null, 2), usage);# Python 3.8+ (pip install requests). Run: FLATKEY_API_KEY=... python jev.py
import json, os, requests
body = json.loads(r"""{
"model": "typesafe/jev-1.13",
"state": "Goal: update staging deploy and verify health check returns 200. Agent steps: (1) ran git pull on staging host, (2) restarted the service, (3) claimed \"deploy complete and healthy\". Missing: no curl or health-check command was run; last log line is only the restart. Required verification step was skipped. Retries so far: 0.",
"questions": {
"verdict": {
"type": "choice",
"instructions": "Judge the agent run against the stated goal and required checks.",
"criteria": {
"pass": "The agent completed the goal and met the required verification steps with supporting evidence",
"retry": "The run is incomplete or skipped a required check, but another attempt with the same setup is warranted",
"fail": "The agent clearly missed the goal, violated policy, or produced incorrect or unsafe output",
"inconclusive": "The transcript lacks enough evidence to judge pass or fail"
}
},
"quality": {
"type": "score",
"instructions": "Overall run quality ignoring self-claims of success.",
"criteria": [
"poor",
"fair",
"good",
"excellent"
]
},
"needs_human_review": {
"type": "noul",
"instructions": "A human or chat-model judge should review this run before the score is trusted."
}
}
}""")
res = requests.post(
"https://router.flatkey.ai/api/alpha/decisions",
headers={"Authorization": f"Bearer {os.environ['FLATKEY_API_KEY']}"},
json=body,
timeout=60,
)
res.raise_for_status()
data = res.json()
print(json.dumps(data["answers"], indent=2), data.get("usage"))No Flatkey key yet? Get one for Jev 1.13 →
About this use case
Who / when
Audience
- teams building agent eval and CI quality gates
- platform engineers replacing LLM-as-judge with a typed scorer
- builders who need stable pass / retry / fail signals at volume
Triggers
- an LLM judge writes long reasoning and drifts run-to-run
- you need a cheap pass / retry / fail / inconclusive call after every agent run
- eval latency or cost is dominated by chat-model judges
- you want auto-record only when confidence is high
The workflow
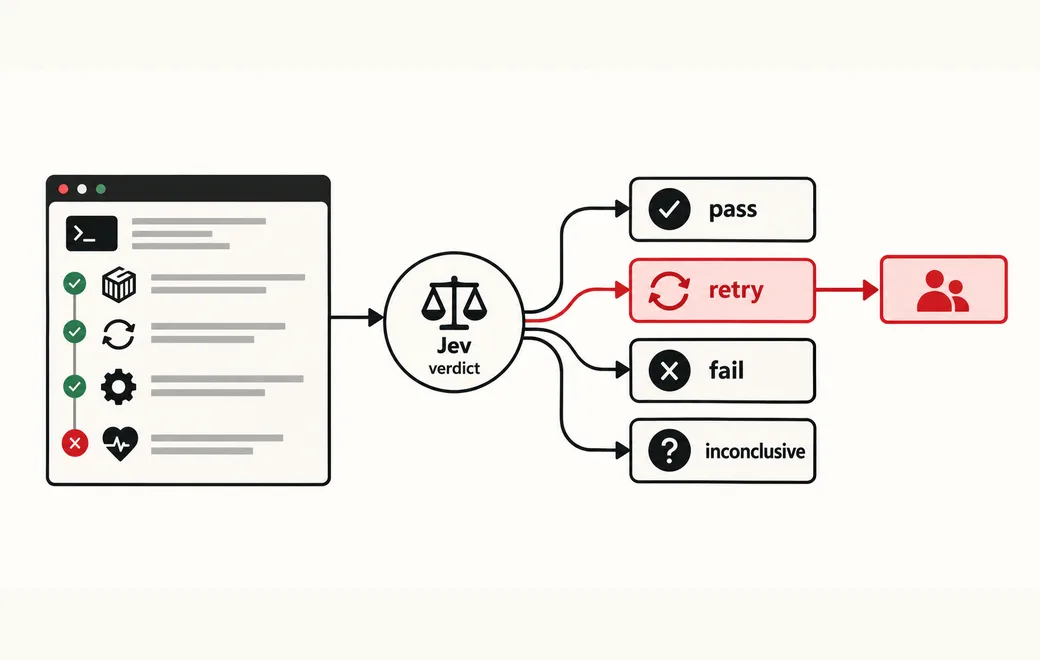
- 01Run transcriptGoal, steps, claims and evidenceInput
- 02Verdictpass / retry / fail / inconclusiveJev
- 03Qualitypoor / fair / good / excellentJev
- 04Confidence gateRecord, second-judge or escalateYour code
Question shape
{
  "verdict": {
    "type": "choice",
    "instructions": "Judge the agent run against the stated goal and required checks.",
    "criteria": {
      "pass": "The agent completed the goal and met the required verification steps with supporting evidence",
      "retry": "The run is incomplete or skipped a required check, but another attempt with the same setup is warranted",
      "fail": "The agent clearly missed the goal, violated policy, or produced incorrect or unsafe output",
      "inconclusive": "The transcript lacks enough evidence to judge pass or fail"
    }
  },
  "quality": {
    "type": "score",
    "instructions": "Overall run quality ignoring self-claims of success.",
    "criteria": [
      "poor",
      "fair",
      "good",
      "excellent"
    ]
  },
  "needs_human_review": {
    "type": "noul",
    "instructions": "A human or chat-model judge should review this run before the score is trusted."
  }
}
Gate policy
≥ 0.90
Auto-record the verdict and quality score in the eval log.
0.65–0.90
Send to a second judge or a human before recording.
< 0.65
Escalate to a human or chat-model judge; do not auto-record.
Failure modes
Pre-launch checks before you trust auto-routing:
- Transcripts that only contain the agent's self-claim of success with no tool output;
- Eval rubrics that change between runs (keep criteria fixed for stable scores);
- Prompt injection in tool stdout, logs or retrieved documents inside the run;
- Using a chat model to rewrite the judge's long reasoning after a typed score;
FAQ
Why use Jev instead of another LLM as judge?
Most LLM evals ask a chat model to read a run, write reasoning, then emit a score—and the score drifts. LangChain tested Jev as the judge instead: about 0.44s per call with dramatically lower scoring variance. A typed Choice / Score / Noul layer behaves more like a measurement instrument than another chatbot.
How should I gate the judge output?
Auto-record when confidence is ≥ 0.90. Between 0.65 and 0.90, send the run to a second judge or a human. Below 0.65, escalate to a human or chat-model judge and do not auto-record.
Can I bring my own API key?
Yes. Try the free demo above without signing in. To run it live on your own text, sign in with Google and connect a Flatkey or OpenRouter key (a quick test call runs when you save it). Manage or delete it anytime under Dashboard → BYOK. Keys are stored encrypted on the server, used only for runs you trigger, and never sent back to the browser. Need a Flatkey key? Get one for Jev 1.13 on Flatkey.
Is this the official TypeSafe Jev product page?
No. jev-llm.com is an independent research and practice site. Verify pricing, models and terms at the original TypeSafe sources.
Sources
A weird use for Jev might end up being one of the best ones: judging other agents. Most LLM evals work by asking another LLM to read a run, think about it, write some reasoning, and finally produce a score… LangChain tested Jev as the judge instead. In their experiment it averaged 0.44s per call, and its scoring variance was dramatically lower… Maybe an evaluator shouldn’t be another chatbot. Maybe it should behave more like a measurement instrument.
— @anilkalm View the post on X →
Wire this gate with your own key
Bring your own key through Flatkey / OpenRouter. Keep exact checks in code.