Try it
Copy the code ↓- Data source
- Decision schema
- Model inference
- Structured result
2 Decision schema 3 typed questions
next_movechoicerespond_nowkeep_listeningbackchannelturn_completenoulprobability 0–1completenessscorelowmediumhigh
3 Model inference typesafe/jev-1.13
Waiting for a run.
4 Structured result
Raw JSON
Run the demo to see the JSON answers, the highlighted pick and the final action.
FLATKEY_API_KEY and run.curl -sS https://router.flatkey.ai/api/alpha/decisions \
-H "Authorization: Bearer $FLATKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "typesafe/jev-1.13",
"state": "Agent'\''s last prompt:\n \"What day and time would you like the table?\"\n\nCaller transcript (silence 420 ms):\n \"Table for four on, uh…\"\n\nTask: next_move (respond_now / keep_listening / backchannel), turn_complete, completeness.",
"questions": {
"next_move": {
"type": "choice",
"instructions": "The caller has just gone quiet on a voice call. Based only on the agent'\''s last prompt and the caller'\''s transcript so far, what should the voice agent do now?",
"criteria": {
"respond_now": "The caller has finished a complete request, answer, or question; the agent should start replying immediately",
"keep_listening": "The utterance is clearly unfinished—trailing filler, a dangling preposition or conjunction, a list in progress, or a self-correction—so the agent should stay silent and wait",
"backchannel": "The caller is mid-story or giving details in pieces; a short acknowledgement like \"mm-hm\" keeps them talking without taking the turn"
}
},
"turn_complete": {
"type": "noul",
"instructions": "The caller has finished their turn and expects the agent to speak now—true only when the transcript reads as a complete thought that needs a reply."
},
"completeness": {
"type": "score",
"instructions": "How semantically complete is the caller'\''s utterance as an answer to the agent'\''s last prompt?",
"criteria": [
"low",
"medium",
"high"
]
}
}
}'// Node.js 18+ (built-in fetch). Run: FLATKEY_API_KEY=... node jev.mjs
const body = {
"model": "typesafe/jev-1.13",
"state": "Agent's last prompt:\n \"What day and time would you like the table?\"\n\nCaller transcript (silence 420 ms):\n \"Table for four on, uh…\"\n\nTask: next_move (respond_now / keep_listening / backchannel), turn_complete, completeness.",
"questions": {
"next_move": {
"type": "choice",
"instructions": "The caller has just gone quiet on a voice call. Based only on the agent's last prompt and the caller's transcript so far, what should the voice agent do now?",
"criteria": {
"respond_now": "The caller has finished a complete request, answer, or question; the agent should start replying immediately",
"keep_listening": "The utterance is clearly unfinished—trailing filler, a dangling preposition or conjunction, a list in progress, or a self-correction—so the agent should stay silent and wait",
"backchannel": "The caller is mid-story or giving details in pieces; a short acknowledgement like \"mm-hm\" keeps them talking without taking the turn"
}
},
"turn_complete": {
"type": "noul",
"instructions": "The caller has finished their turn and expects the agent to speak now—true only when the transcript reads as a complete thought that needs a reply."
},
"completeness": {
"type": "score",
"instructions": "How semantically complete is the caller's utterance as an answer to the agent's last prompt?",
"criteria": [
"low",
"medium",
"high"
]
}
}
};
const res = await fetch("https://router.flatkey.ai/api/alpha/decisions", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.FLATKEY_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify(body),
});
if (!res.ok) throw new Error(`Jev request failed: ${res.status} ${await res.text()}`);
const { answers, usage } = await res.json();
console.log(JSON.stringify(answers, null, 2), usage);# Python 3.8+ (pip install requests). Run: FLATKEY_API_KEY=... python jev.py
import json, os, requests
body = json.loads(r"""{
"model": "typesafe/jev-1.13",
"state": "Agent's last prompt:\n \"What day and time would you like the table?\"\n\nCaller transcript (silence 420 ms):\n \"Table for four on, uh…\"\n\nTask: next_move (respond_now / keep_listening / backchannel), turn_complete, completeness.",
"questions": {
"next_move": {
"type": "choice",
"instructions": "The caller has just gone quiet on a voice call. Based only on the agent's last prompt and the caller's transcript so far, what should the voice agent do now?",
"criteria": {
"respond_now": "The caller has finished a complete request, answer, or question; the agent should start replying immediately",
"keep_listening": "The utterance is clearly unfinished—trailing filler, a dangling preposition or conjunction, a list in progress, or a self-correction—so the agent should stay silent and wait",
"backchannel": "The caller is mid-story or giving details in pieces; a short acknowledgement like \"mm-hm\" keeps them talking without taking the turn"
}
},
"turn_complete": {
"type": "noul",
"instructions": "The caller has finished their turn and expects the agent to speak now—true only when the transcript reads as a complete thought that needs a reply."
},
"completeness": {
"type": "score",
"instructions": "How semantically complete is the caller's utterance as an answer to the agent's last prompt?",
"criteria": [
"low",
"medium",
"high"
]
}
}
}""")
res = requests.post(
"https://router.flatkey.ai/api/alpha/decisions",
headers={"Authorization": f"Bearer {os.environ['FLATKEY_API_KEY']}"},
json=body,
timeout=60,
)
res.raise_for_status()
data = res.json()
print(json.dumps(data["answers"], indent=2), data.get("usage"))No Flatkey key yet? Get one for Jev 1.13 →
About this use case
Who / when
Audience
- voice-agent builders on Pipecat, LiveKit, or a custom STT → LLM → TTS loop
- teams tuning the pause between the caller stopping and the agent replying
- support and booking bots that keep cutting callers off mid-sentence
Triggers
- speech-to-text reports silence or an end-of-utterance event
- a fixed silence timeout either feels slow or interrupts people who are thinking
- trailing words like "um", "and", or "on, uh…" signal the caller is not finished
- waiting for the main LLM to decide adds hundreds of milliseconds to every turn
The workflow
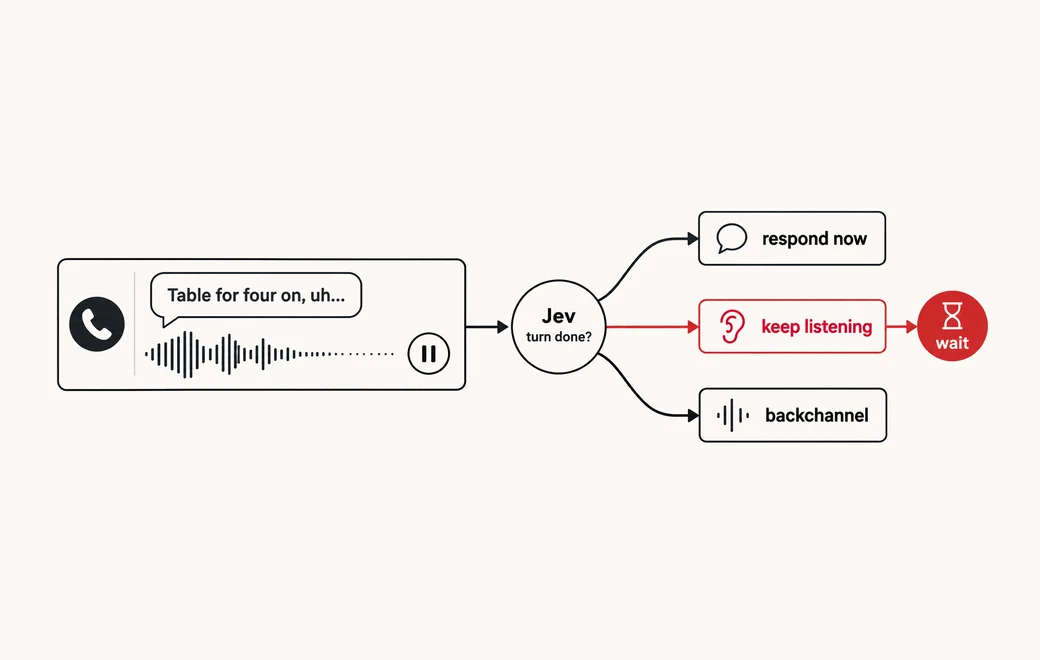
- 01Pause + transcriptSilence event, last words, agent promptInput
- 02Next moverespond / keep listening / backchannelJev
- 03Turn complete?Yes/no + completeness scoreJev
- 04Code gateSpeak, wait, or say "mm-hm"Your code
Question shape
{
  "next_move": {
    "type": "choice",
    "instructions": "The caller has just gone quiet on a voice call. Based only on the agent's last prompt and the caller's transcript so far, what should the voice agent do now?",
    "criteria": {
      "respond_now": "The caller has finished a complete request, answer, or question; the agent should start replying immediately",
      "keep_listening": "The utterance is clearly unfinished—trailing filler, a dangling preposition or conjunction, a list in progress, or a self-correction—so the agent should stay silent and wait",
      "backchannel": "The caller is mid-story or giving details in pieces; a short acknowledgement like \"mm-hm\" keeps them talking without taking the turn"
    }
  },
  "turn_complete": {
    "type": "noul",
    "instructions": "The caller has finished their turn and expects the agent to speak now—true only when the transcript reads as a complete thought that needs a reply."
  },
  "completeness": {
    "type": "score",
    "instructions": "How semantically complete is the caller's utterance as an answer to the agent's last prompt?",
    "criteria": [
      "low",
      "medium",
      "high"
    ]
  }
}
Gate policy
≥ 0.90
Honor next_move: start TTS on respond_now, stay silent on keep_listening, or play a short backchannel and keep the mic open.
0.65–0.90
Respond only when turn_complete is true; otherwise wait one short extra beat (e.g. 300 ms) and re-ask on the updated transcript.
< 0.65
Fall back to your silence timeout and log the transcript and probabilities for tuning.
Failure modes
Pre-launch checks before you trust auto-routing:
- Replying the moment silence hits, so callers who pause to think get cut off mid-sentence;
- A long fixed timeout on every turn, so the agent feels slow even when the caller clearly finished;
- Sending every pause to the main chat model and adding a full LLM round trip before the agent can speak;
- Backchanneling so often that "mm-hm" becomes noise, or on a question that needed a real answer;
- Letting Jev drive audio directly—it only answers the turn question; barge-in, VAD, and TTS control stay in code;
FAQ
Why is turn-taking a classifier problem?
Most of the pause after a caller stops talking is the agent deciding whether they are done. That is one yes/no-shaped question over the transcript so far, not a generation task, so a small decision model can answer it without waiting on the main LLM.
Does this replace voice activity detection or my STT's end-of-turn events?
No. Keep VAD and your speech-to-text events (for example Deepgram Flux turn events) as the trigger. Jev adds the semantic check on what was said, so "Table for four on, uh…" waits while "Thursday at seven, please." gets an instant reply.
What does the Flatkey call look like?
POST https://router.flatkey.ai/api/alpha/decisions with Authorization: Bearer …, Content-Type: application/json, and a body of state, model (typesafe/jev-1.13), and questions (choice / score / noul). This is not an OpenAI-compatible /v1 chat endpoint.
What should happen when Jev is unsure?
Treat low confidence as "use the old rule": fall back to your silence timeout and log the case. In the middle band, wait a short extra beat and ask again on the updated transcript, which usually settles the call.
Can I bring my own API key?
Yes. Try the free demo above without signing in. To run it live on your own text, sign in with Google and connect a Flatkey or OpenRouter key (a quick test call runs when you save it). Manage or delete it anytime under Dashboard → BYOK. Keys are stored encrypted on the server, used only for runs you trigger, and never sent back to the browser. Need a Flatkey key? Get one for Jev 1.13 on Flatkey.
Is this the official TypeSafe Jev product page?
No. jev-llm.com is an independent research and practice site. Verify pricing, models and terms at the original TypeSafe sources.
Sources
I wanted to know what a classifier does to a voice agent. So I spent two days timing one with Deepgram Flux STT, Pipecat 1.12, Haiku, Jev and OpenAI's Luna. Most of the pause after you stop talking is one yes/no question, and it's fixable. No code 👇
— @coreylweathers View the post on X →
Wire this gate with your own key
Bring your own key through Flatkey / OpenRouter. Keep exact checks in code.