Try it
Copy the code ↓- Data source
- Decision schema
- Model inference
- Structured result
2 Decision schema 3 typed questions
judgmentchoicepassblockreviewevidence_strengthscorenoneweakmoderatestrongneeds_humannoulprobability 0–1
3 Model inference typesafe/jev-1.13
Waiting for a run.
4 Structured result
Raw JSON
Run the demo to see the JSON answers, the highlighted pick and the final action.
FLATKEY_API_KEY and run.curl -sS https://router.flatkey.ai/api/alpha/decisions \
-H "Authorization: Bearer $FLATKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "typesafe/jev-1.13",
"state": "Claim: \"Jev checked 3,157 claims against sources with 78.9% balanced accuracy at roughly 0.2s per verdict and about 14 cents total cost.\"\n\nSource A: Blog excerpt — \"We evaluated mute probability models on 3,157 claim–source pairs. Balanced accuracy: 78.9%. Median latency ~0.2s. Total spend across the run: $0.14.\"\n\nSource B: Same post — \"Judgments collapse when evidence is missing or wrong; calibrate thresholds and cascade pass/block/review.\"\n\nTask: judge grounding of the claim against these sources only.",
"questions": {
"judgment": {
"type": "choice",
"instructions": "Judge whether the claim is grounded in the provided source evidence. Ignore world knowledge outside the snippets.",
"criteria": {
"pass": "The sources support the claim with enough specific evidence; no material contradiction",
"block": "The sources contradict the claim, or the claim asserts facts the sources do not support",
"review": "Evidence is partial, ambiguous, or conflicting enough that a human should decide"
}
},
"evidence_strength": {
"type": "score",
"instructions": "How strong is the source support (or contradiction) for this claim, ignoring the claim author'\''s confidence.",
"criteria": [
"none",
"weak",
"moderate",
"strong"
]
},
"needs_human": {
"type": "noul",
"instructions": "A human should review this claim–source pair before the judgment is trusted in production."
}
}
}'// Node.js 18+ (built-in fetch). Run: FLATKEY_API_KEY=... node jev.mjs
const body = {
"model": "typesafe/jev-1.13",
"state": "Claim: \"Jev checked 3,157 claims against sources with 78.9% balanced accuracy at roughly 0.2s per verdict and about 14 cents total cost.\"\n\nSource A: Blog excerpt — \"We evaluated mute probability models on 3,157 claim–source pairs. Balanced accuracy: 78.9%. Median latency ~0.2s. Total spend across the run: $0.14.\"\n\nSource B: Same post — \"Judgments collapse when evidence is missing or wrong; calibrate thresholds and cascade pass/block/review.\"\n\nTask: judge grounding of the claim against these sources only.",
"questions": {
"judgment": {
"type": "choice",
"instructions": "Judge whether the claim is grounded in the provided source evidence. Ignore world knowledge outside the snippets.",
"criteria": {
"pass": "The sources support the claim with enough specific evidence; no material contradiction",
"block": "The sources contradict the claim, or the claim asserts facts the sources do not support",
"review": "Evidence is partial, ambiguous, or conflicting enough that a human should decide"
}
},
"evidence_strength": {
"type": "score",
"instructions": "How strong is the source support (or contradiction) for this claim, ignoring the claim author's confidence.",
"criteria": [
"none",
"weak",
"moderate",
"strong"
]
},
"needs_human": {
"type": "noul",
"instructions": "A human should review this claim–source pair before the judgment is trusted in production."
}
}
};
const res = await fetch("https://router.flatkey.ai/api/alpha/decisions", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.FLATKEY_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify(body),
});
if (!res.ok) throw new Error(`Jev request failed: ${res.status} ${await res.text()}`);
const { answers, usage } = await res.json();
console.log(JSON.stringify(answers, null, 2), usage);# Python 3.8+ (pip install requests). Run: FLATKEY_API_KEY=... python jev.py
import json, os, requests
body = json.loads(r"""{
"model": "typesafe/jev-1.13",
"state": "Claim: \"Jev checked 3,157 claims against sources with 78.9% balanced accuracy at roughly 0.2s per verdict and about 14 cents total cost.\"\n\nSource A: Blog excerpt — \"We evaluated mute probability models on 3,157 claim–source pairs. Balanced accuracy: 78.9%. Median latency ~0.2s. Total spend across the run: $0.14.\"\n\nSource B: Same post — \"Judgments collapse when evidence is missing or wrong; calibrate thresholds and cascade pass/block/review.\"\n\nTask: judge grounding of the claim against these sources only.",
"questions": {
"judgment": {
"type": "choice",
"instructions": "Judge whether the claim is grounded in the provided source evidence. Ignore world knowledge outside the snippets.",
"criteria": {
"pass": "The sources support the claim with enough specific evidence; no material contradiction",
"block": "The sources contradict the claim, or the claim asserts facts the sources do not support",
"review": "Evidence is partial, ambiguous, or conflicting enough that a human should decide"
}
},
"evidence_strength": {
"type": "score",
"instructions": "How strong is the source support (or contradiction) for this claim, ignoring the claim author's confidence.",
"criteria": [
"none",
"weak",
"moderate",
"strong"
]
},
"needs_human": {
"type": "noul",
"instructions": "A human should review this claim–source pair before the judgment is trusted in production."
}
}
}""")
res = requests.post(
"https://router.flatkey.ai/api/alpha/decisions",
headers={"Authorization": f"Bearer {os.environ['FLATKEY_API_KEY']}"},
json=body,
timeout=60,
)
res.raise_for_status()
data = res.json()
print(json.dumps(data["answers"], indent=2), data.get("usage"))No Flatkey key yet? Get one for Jev 1.13 →
About this use case
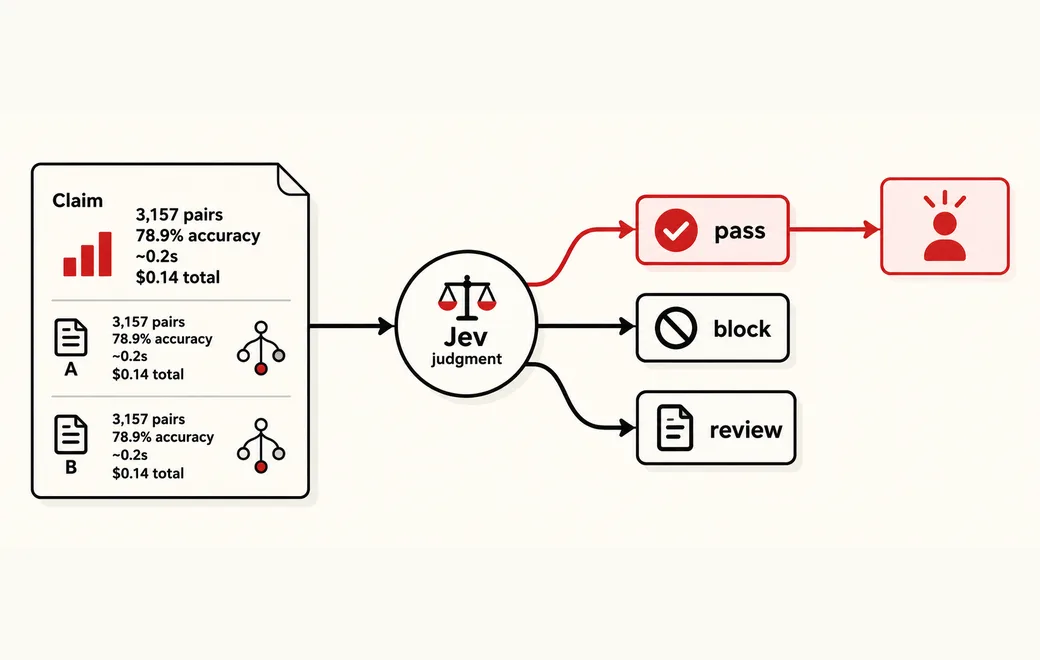
Who / when
Audience
- teams building RAG answer gates and citation checkers
- eval engineers replacing chatty LLM-as-judge with a typed scorer
- builders who need cheap pass / block / review signals on claims at volume
Triggers
- an LLM judge writes long reasoning and still hallucinates about grounding
- you need a cheap pass / block / review call after every claim–source pair
- judgments collapse when evidence is missing or wrong and you need calibrated thresholds
- you want auto-accept only when evidence strength and confidence are both high
The workflow
- 01Claim + sourcesClaim text and supporting or contradicting snippetsInput
- 02Judgmentpass / block / reviewJev
- 03Evidence strengthnone / weak / moderate / strongJev
- 04Cascade gateAccept, block, or route to humanYour code
Question shape
{
  "judgment": {
    "type": "choice",
    "instructions": "Judge whether the claim is grounded in the provided source evidence. Ignore world knowledge outside the snippets.",
    "criteria": {
      "pass": "The sources support the claim with enough specific evidence; no material contradiction",
      "block": "The sources contradict the claim, or the claim asserts facts the sources do not support",
      "review": "Evidence is partial, ambiguous, or conflicting enough that a human should decide"
    }
  },
  "evidence_strength": {
    "type": "score",
    "instructions": "How strong is the source support (or contradiction) for this claim, ignoring the claim author's confidence.",
    "criteria": [
      "none",
      "weak",
      "moderate",
      "strong"
    ]
  },
  "needs_human": {
    "type": "noul",
    "instructions": "A human should review this claim–source pair before the judgment is trusted in production."
  }
}
Gate policy
≥ 0.90
Auto-accept only when judgment is pass and evidence_strength is moderate or strong.
0.65–0.90
Cascade to a human or stronger judge; treat as review even if the top choice is pass.
< 0.65
Block the claim or answer; require better sources or a rewrite (also when judgment is block).
Failure modes
Pre-launch checks before you trust auto-routing:
- Claims judged without any source snippets (judgments collapse when evidence is missing);
- Wrong or swapped sources that look plausible but do not actually support the claim;
- Prompt injection inside retrieved documents that tries to force a pass;
- Using a chat model to rewrite long free-form justification after a typed judgment;
FAQ
Why use Jev instead of another LLM as a grounding judge?
Chatty LLM-as-judge setups often write long reasoning and still drift. Mute models that only answer in probabilities were tested on thousands of claim–source pairs with ~78.9% accuracy, ~0.2s verdicts and cents-level cost. A typed Choice / Score / Noul layer behaves more like a measurement instrument than another chatbot.
How should I cascade pass / block / review?
Auto-accept only on pass with high confidence and moderate/strong evidence. Route review (or mid-confidence) to a human or stronger judge. Block on contradiction, missing evidence, or low confidence—and recalibrate thresholds when judgments collapse without real sources.
Can I bring my own API key?
Yes. Try the free demo above without signing in. To run it live on your own text, sign in with Google and connect a Flatkey or OpenRouter key (a quick test call runs when you save it). Manage or delete it anytime under Dashboard → BYOK. Keys are stored encrypted on the server, used only for runs you trigger, and never sent back to the browser. Need a Flatkey key? Get one for Jev 1.13 on Flatkey.
Is this the official TypeSafe Jev product page?
No. jev-llm.com is an independent research and practice site. Verify pricing, models and terms at the original TypeSafe sources.
Sources
"LLM-as-a-judge" is just two chatbots gaslighting each other at $0.03/token. We tested Jev & Laya—two mute models that only answer in probabilities. 78.9% accuracy. 0.2s verdicts. 14 cents total.
— @vignesh_bkn View the post on X →
Wire this gate with your own key
Bring your own key through Flatkey / OpenRouter. Keep exact checks in code.