Try it
Copy the code ↓- Data source
- Decision schema
- Model inference
- Structured result
2 Decision schema 3 typed questions
need_typechoiceintegrationreliabilitypricingworkflow_gapusabilityotherseverityscoreminorannoyingpainfulblockingsolved_by_launchesnoulprobability 0–1
3 Model inference typesafe/jev-1.13
Waiting for a run.
4 Structured result
Raw JSON
Run the demo to see the JSON answers, the highlighted pick and the final action.
FLATKEY_API_KEY and run.curl -sS https://router.flatkey.ai/api/alpha/decisions \
-H "Authorization: Bearer $FLATKEY_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "typesafe/jev-1.13",
"state": "Need: Stripe → QuickBooks invoice export keeps breaking\n\nSample complaints (38 in 90 days):\n- \"Every month-end the sync drops half the invoices and I re-enter them by hand.\"\n- \"Our bookkeeper spends a full day fixing duplicated Stripe payouts in QBO.\"\n\nRecent launches (12 months): 1 — a Zapier template for Stripe → Google Sheets.\n\nTask: need_type, severity, solved_by_launches.",
"questions": {
"need_type": {
"type": "choice",
"instructions": "What kind of product need do these complaints describe?",
"criteria": {
"integration": "Two tools do not connect, sync, import, or export data reliably",
"reliability": "A product the user already has is buggy, slow, or loses data",
"pricing": "The product works but costs too much or the pricing model does not fit",
"workflow_gap": "No tool covers a step of the user'\''s job, so they do it by hand or in spreadsheets",
"usability": "The capability exists but is confusing, hidden, or hard to set up",
"other": "None of these"
}
},
"severity": {
"type": "score",
"instructions": "How severe is the pain for the people complaining, judged only from what they wrote?",
"criteria": [
"minor",
"annoying",
"painful",
"blocking"
]
},
"solved_by_launches": {
"type": "noul",
"instructions": "At least one of the listed recent launches already solves this need as the complainers describe it—true only when a launch clearly addresses the same problem for the same users."
}
}
}'// Node.js 18+ (built-in fetch). Run: FLATKEY_API_KEY=... node jev.mjs
const body = {
"model": "typesafe/jev-1.13",
"state": "Need: Stripe → QuickBooks invoice export keeps breaking\n\nSample complaints (38 in 90 days):\n- \"Every month-end the sync drops half the invoices and I re-enter them by hand.\"\n- \"Our bookkeeper spends a full day fixing duplicated Stripe payouts in QBO.\"\n\nRecent launches (12 months): 1 — a Zapier template for Stripe → Google Sheets.\n\nTask: need_type, severity, solved_by_launches.",
"questions": {
"need_type": {
"type": "choice",
"instructions": "What kind of product need do these complaints describe?",
"criteria": {
"integration": "Two tools do not connect, sync, import, or export data reliably",
"reliability": "A product the user already has is buggy, slow, or loses data",
"pricing": "The product works but costs too much or the pricing model does not fit",
"workflow_gap": "No tool covers a step of the user's job, so they do it by hand or in spreadsheets",
"usability": "The capability exists but is confusing, hidden, or hard to set up",
"other": "None of these"
}
},
"severity": {
"type": "score",
"instructions": "How severe is the pain for the people complaining, judged only from what they wrote?",
"criteria": [
"minor",
"annoying",
"painful",
"blocking"
]
},
"solved_by_launches": {
"type": "noul",
"instructions": "At least one of the listed recent launches already solves this need as the complainers describe it—true only when a launch clearly addresses the same problem for the same users."
}
}
};
const res = await fetch("https://router.flatkey.ai/api/alpha/decisions", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.FLATKEY_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify(body),
});
if (!res.ok) throw new Error(`Jev request failed: ${res.status} ${await res.text()}`);
const { answers, usage } = await res.json();
console.log(JSON.stringify(answers, null, 2), usage);# Python 3.8+ (pip install requests). Run: FLATKEY_API_KEY=... python jev.py
import json, os, requests
body = json.loads(r"""{
"model": "typesafe/jev-1.13",
"state": "Need: Stripe → QuickBooks invoice export keeps breaking\n\nSample complaints (38 in 90 days):\n- \"Every month-end the sync drops half the invoices and I re-enter them by hand.\"\n- \"Our bookkeeper spends a full day fixing duplicated Stripe payouts in QBO.\"\n\nRecent launches (12 months): 1 — a Zapier template for Stripe → Google Sheets.\n\nTask: need_type, severity, solved_by_launches.",
"questions": {
"need_type": {
"type": "choice",
"instructions": "What kind of product need do these complaints describe?",
"criteria": {
"integration": "Two tools do not connect, sync, import, or export data reliably",
"reliability": "A product the user already has is buggy, slow, or loses data",
"pricing": "The product works but costs too much or the pricing model does not fit",
"workflow_gap": "No tool covers a step of the user's job, so they do it by hand or in spreadsheets",
"usability": "The capability exists but is confusing, hidden, or hard to set up",
"other": "None of these"
}
},
"severity": {
"type": "score",
"instructions": "How severe is the pain for the people complaining, judged only from what they wrote?",
"criteria": [
"minor",
"annoying",
"painful",
"blocking"
]
},
"solved_by_launches": {
"type": "noul",
"instructions": "At least one of the listed recent launches already solves this need as the complainers describe it—true only when a launch clearly addresses the same problem for the same users."
}
}
}""")
res = requests.post(
"https://router.flatkey.ai/api/alpha/decisions",
headers={"Authorization": f"Bearer {os.environ['FLATKEY_API_KEY']}"},
json=body,
timeout=60,
)
res.raise_for_status()
data = res.json()
print(json.dumps(data["answers"], indent=2), data.get("usage"))No Flatkey key yet? Get one for Jev 1.13 →
About this use case
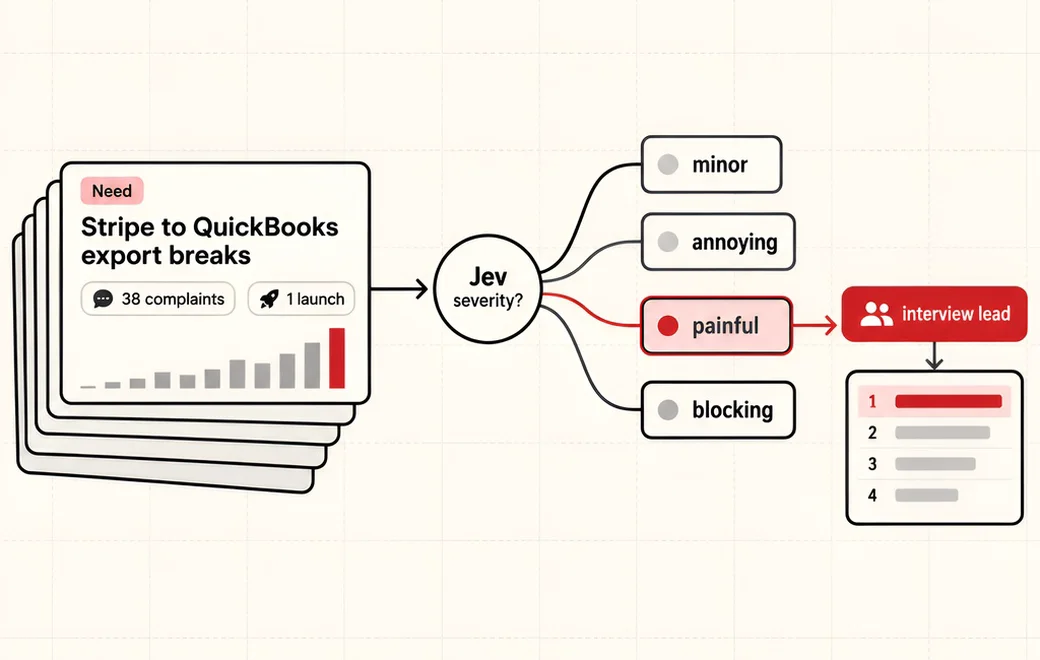
Who / when
Audience
- founders and PMs mining Reddit, reviews, and support threads for problems worth building
- product-discovery and market-research teams scoring opportunity backlogs
- indie hackers who want interview leads without paying frontier-model prices per row
Triggers
- you have hundreds of complaint clusters and no consistent way to compare them
- stakeholders want to re-weight growth vs. severity and see the ranking move
- classifying every need with a chat model is projected to cost thousands of dollars
- you need to know which pains already have recent launches and which are wide open
The workflow
- 01Need + evidenceNeed summary, sample complaints, recent launchesInput
- 02Need typeintegration / reliability / pricing / workflow …Jev
- 03Severity + coverageHow painful, and do launches already solve it?Jev
- 04Weighted rankCode mixes user weights with counts and growthYour code
Question shape
{
  "need_type": {
    "type": "choice",
    "instructions": "What kind of product need do these complaints describe?",
    "criteria": {
      "integration": "Two tools do not connect, sync, import, or export data reliably",
      "reliability": "A product the user already has is buggy, slow, or loses data",
      "pricing": "The product works but costs too much or the pricing model does not fit",
      "workflow_gap": "No tool covers a step of the user's job, so they do it by hand or in spreadsheets",
      "usability": "The capability exists but is confusing, hidden, or hard to set up",
      "other": "None of these"
    }
  },
  "severity": {
    "type": "score",
    "instructions": "How severe is the pain for the people complaining, judged only from what they wrote?",
    "criteria": [
      "minor",
      "annoying",
      "painful",
      "blocking"
    ]
  },
  "solved_by_launches": {
    "type": "noul",
    "instructions": "At least one of the listed recent launches already solves this need as the complainers describe it—true only when a launch clearly addresses the same problem for the same users."
  }
}
Gate policy
≥ 0.90
Write the labels; include the need in the weighted ranking and the interview-lead export.
0.65–0.90
Rank it, but mark the row for a quick human glance before it goes into interview outreach.
< 0.65
Keep it out of the ranking and send it to a review queue—usually the need summary mixes two problems.
Failure modes
Pre-launch checks before you trust auto-routing:
- Letting Jev compute the ranking—counts, growth rates, and weights are arithmetic and belong in code;
- Feeding a need summary that mixes two different problems, so every label comes back unsure;
- Treating "a launch exists" as "solved" when the launch targets different users or a different step;
- Asking a chat model to classify each row and paying hundreds of times more for the same labels;
- Re-running classification every time someone moves a weight slider instead of caching the labels;
FAQ
Why use Jev instead of a chat model for this?
Each need is the same three short questions over a small block of text. That is a classification job, not generation. In the source post, classifying 149 needs cost about $22.51 in Jev credit versus an estimated $5.8k with existing LLMs—roughly 250× cheaper.
How do user-tunable weights fit in?
Jev labels each need once (type, severity, coverage). Your code turns those labels plus hard data—complaint count, growth, launch count—into numbers and computes a weighted score, e.g. w_growth × growth + w_severity × severity + w_gap × (1 − solved). Moving a weight re-sorts instantly with no new model calls.
What does the Flatkey call look like?
POST https://router.flatkey.ai/api/alpha/decisions with Authorization: Bearer …, Content-Type: application/json, and a body of state, model (typesafe/jev-1.13), and questions (choice / score / noul). This is not an OpenAI-compatible /v1 chat endpoint.
What should happen when Jev is unsure?
Low confidence usually means the need summary bundles two problems or the complaints are vague. Keep those rows out of the ranking, split or rewrite the summary, and re-ask—it is cheap enough to run twice.
Can I bring my own API key?
Yes. Try the free demo above without signing in. To run it live on your own text, sign in with Google and connect a Flatkey or OpenRouter key (a quick test call runs when you save it). Manage or delete it anytime under Dashboard → BYOK. Keys are stored encrypted on the server, used only for runs you trigger, and never sent back to the browser. Need a Flatkey key? Get one for Jev 1.13 on Flatkey.
Is this the official TypeSafe Jev product page?
No. jev-llm.com is an independent research and practice site. Verify pricing, models and terms at the original TypeSafe sources.
Sources
I put 149 needs on the site, with the complaint and launch data. You can change the weights and watch the ranking move. Give more weight to growth, severity, or problems getting few launches. I spent only $22.51 in TypeSafe Jev credit on the classification. The study covers Sep 28, 2025 through Sep 28, 2026. Smaller model like Jev really change the cost here. I expect to spend up to $5.8k (250x more expensive) if using existing LLMs. These are leads for interviews.
— @hansel_hansl View the post on X →
Wire this gate with your own key
Bring your own key through Flatkey / OpenRouter. Keep exact checks in code.